
Course Resources
Resources for teaching our High School Statistics curriculum.
- Lesson Flow - timing and flow of class, using our lesson materials
- Pacing Guide - pacing our units, with daily or block schedules
- Alignment Guide - aligning our lessons to national and state standards for high school statistics
- Classroom Routines - a guidebook of classroom routines embedded within our lessons
Teaching Resources
Resources for teaching with Skew The Script.
- Discussion Norms - our model discussion norms for the classroom
- Letter to Parents - letter to share with parents about our nonpartisan approach
- Teaching Math on Civic Topics - tips for teaching math lessons that cover civic topics
Lesson Notes
Lesson-specific insights from the creators of this lesson.
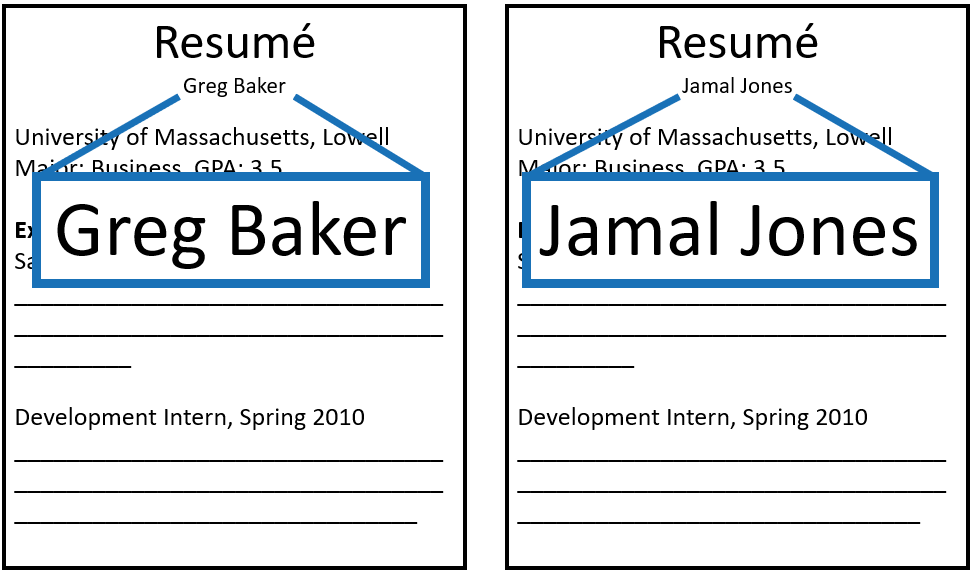
This lesson returns to a context covered in a prior lesson: an experiment in which researchers sent fake, identical resumés to employers. The resumés only differed in one aspect: the applicant’s name. Half of the resumés had a commonly-white name and half had a commonly-black name (as determined by birth certificate records). In the prior lesson about this study, students used a hypothesis test to evaluate the experiment’s results. In this lesson, they’ll construct a confidence interval to estimate the true difference in callback rates.
- Use simulations to construct a confidence interval for the difference between population proportions
- Interpret a confidence interval for the difference between population proportions
- Connect confidence interval values to the results of hypothesis tests
After developing their understanding of confidence intervals for one proportion (Lessons 5.1 - 5.3), students now construct confidence intervals for the difference between two proportions. Importantly, when working with one proportion, students used a normal curve approximation to construct their confidence intervals. Now in the two proportion setting, they will use computer simulations instead. This shift is done for two reasons: First, the normal curve approximation formula for two proportions and the conditions checks for that formula can be unwieldy. By using computer simulation instead, students can focus on the conceptual skill of interpreting the interval, rather than getting bogged down in procedures. Second, further exposing students to computer simulation methods (which were first introduced in Lessons 4.1, 4.2, and 4.3) gives them a window into more modern approaches for statistical inference.
Before proceeding: Familiarize yourself with the lesson materials linked above (e.g. handout, handout key, slides, video). Then, for additional background and teaching tips from the lesson creators, check out the sections below.
- Although this lesson analyzes the same study as a prior lesson (Lesson 4.7), the materials are designed without presuming that students have seen the prior lesson. Therefore, instructors can use this lesson even if they haven’t used the prior lesson. However, instructors who have used the prior lesson with their students can reduce the discussion of design of the study to a brief resurfacing.
- Because this study is a well-designed experiment with random assignment to treatment, the observed difference in callback rates can be interpreted as a causal effect from the assigned names. That said, the underlying mechanism behind the name advantage is less clear. Intentional racial discrimination is one possible explanation. However, it’s also possible that the differences in callback rates could arise from unintentional biases. For example, commonly-white names may tend to be more familiar for the people making hiring decisions, so hiring managers may unconsciously gravitate to such names. Framing these considerations with students is important for interpreting the study and provides a natural opportunity to revisit the concept of study generalizability. While the experiment supports a causal conclusion, instructors and students can also discuss the extent to which the findings apply to other employers, industries, locations, or stages of the hiring process.
- Before releasing students to do the Practice problems, it’s helpful to point out that each question stem defines the order of subtraction for the proportions in the problem. Reinforcing this will help students’ responses have the same signs (positive or negative), which allows for easier collaboration, interpretation, and checking of solutions.
First, download this lesson's slide deck and handout key to see the prompt and sample responses for the Lesson Starter. Then, check out the additional background notes below.
Instructional routine: Ten-Minute Talk. The lesson provides space for students to jot down their thoughts on the prompt, before discussing with a partner and engaging in whole group discussion. You can find more background on implementing a Ten-Minute talk here.
Purpose & Background: Now that we have come to the final lesson of the course’s statistical inference topics (final lesson for hypothesis tests and confidence intervals), this 10-minute talk provides students with a chance to reflect on their learning. Encouraging students to look through their notes for Unit 4 (Hypothesis Tests) and Unit 5 (Confidence Intervals) may help elicit more precise responses. Instructors can use the students’ responses to design review / synthesis days before the end of unit assessment.
First, download this lesson's handout key and read through its Discussion Question section. Then, check out our model discussion norms and the additional background notes below.
- In general, when the null hypothesis is outside a confidence interval (i.e. the null is not a plausible value), the corresponding hypothesis test would reject it. When the null hypothesis is within a confidence interval (i.e. the null is a plausible value), the corresponding hypothesis test would fail to reject it. This relationship is true in most cases where the significance level (e.g. α = 0.05) of a two-sided hypothesis test is the complement of the confidence level (e.g. 95% confidence).
- The above relationship is not always true, especially when utilizing simulation-based intervals and hypothesis tests. Because results vary across simulations, intervals or tests that are borderline significant (p-values very close to 0.05 or confidence intervals very close to 0) should have more simulations run than usual (e.g. run 1,000 simulations instead of 100) in order to establish a more robustly defined p-value or confidence interval.
- Multiple viewpoints about the broader causes of racial wage gaps may emerge during discussion. The statistical evidence from this experiment supports a causal conclusion about the effect of the assigned names in this particular hiring context. However, broader questions about labor market outcomes may extend beyond the scope of this single study and beyond the scope of this course.
- This lesson is based on a landmark audit study (free working paper version here) by economists Marianne Bertrand and Sendhil Mullainathan. Researchers sent nearly 5,000 fictitious resumés to job advertisements in Chicago and Boston, randomly assigning each resumé either a commonly-white or commonly-black first name. The jobs represented a variety of occupations that required different levels of experience and education, strengthening the study's relevance across multiple hiring settings. The researchers used birth certificate records to identify the names that were most exclusively associated with each racial group. Multiple male and female names were used within each group, helping ensure that the results were not driven by any single name.
- The Bertrand and Mullainathan study became one of the best-known examples of an audit study. Since its publication, researchers have conducted numerous studies using the same basic audit study design in a variety of hiring contexts. Together, these studies illustrate how statistical evidence accumulates through repeated investigation.
- Although students are working with two samples in each problem of this lesson, the parameter of interest is still a single quantity: the difference between the two population proportions. Reinforce that a difference of 0 represents no difference between the populations, while positive and negative values indicate which population has the higher proportion. This also provides a natural opportunity to emphasize the importance of clearly defining the order of subtraction before beginning a two-sample analysis.
- To generate the types of computer simulations we use in the lesson, our preferred tool is stapplet. For simulations comparing two proportions, utilize the One Categorical Variable, Multiple Groups applet. Input the observed data. Then, scroll down to the inference section and choose simulation.
- Technically, because this lesson describes an experiment with random assignment, the distribution of simulations is a randomization distribution rather than a sampling distribution. Randomization distributions describe the results of repeatedly reassigning treatments, whereas sampling distributions describe the results of repeatedly drawing random samples. For these procedures, however, the mathematical results are equivalent, so it is not necessary to formally distinguish between the two.
Student Supports
Lesson-specific resources to support all learners.
- Because both sample proportions are relatively small, it can be helpful to express them as percentages (rather than decimals) before comparing them. Seeing that 10.1% is noticeably larger than 6.7% often makes the direction and size of the observed difference easier to recognize before calculating the difference in proportions.
- Encourage students to define the parameter of interest before beginning calculations. Writing a statement such as “Let p1–p2 represent…” provides a reference point for interpreting positive and negative values consistently throughout the problem.
- When interpreting confidence intervals, encourage students to focus first on whether 0 is a plausible value for the difference, then on what the remaining plausible values suggest about both the direction and magnitude of the effect.
- Vocabulary used in the context of the lesson may include words that are unfamiliar or have several meanings. In particular, the following mathematical terms may need clarification or a definition provided:
- Population proportion
- Margin of error
- Parameter
- In addition, the following contextual terms may need clarification or a definition provided:
- Callback rate
- Resumé
- Hiring